forgetting to redact credentials that made it possible for all of Reddit to log into Epstein’s account and trample over all the evidence
/o\ 🤦
Part of me wants to think this fuck up was on purpose.
Literally stop publicizing this stuff until they’ve shown their entire hands
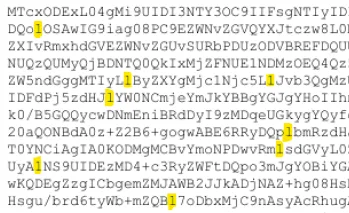
We just need those 76 page base64 printouts stuffed into captcha so we can crowdsource cracking them
I actually like this idea a lot (the crowdfunding part)
crowdsource, not crowdfund. One is sharing the work, the other is sharing the cost.
Is that nitpick really necessary? I would be donating my time, that’s my cost. So crowdfunded wouldn’t even be wrong unless you believe your time to be worthless.
It’s not a nitpick for me but a relevant clarification to distinguish between two very different words.
Amazing what a bit of knowledge, intelligence and competency can achieve.
Inversely, it’s also amazing what a lack thereof cannot achieve, for instance, redacting publicized documents.
…it’s safe to say that Pam Bondi’s DoJ did not put its best and brightest on this (admittedly gargantuan) undertaking
Actually they did. It’s just that their best and brightest are fairly dim.
Their best and brightest were fired or retired.
It could also have been incompetence as a form of resistance, for all we know, or a combination of both.
This. If I didn’t agree with what they’re doing (and I don’t) and I wanted to resist I would do my best to steer towards a reversible redaction method. Then just feign ignorance.
Someone should write an update to the Simple Sabotage Field Manual.
Well it’s all the leftovers at this point. When the priority is loyalty, performance suffers.
I am not intelligent enough to understand any of it but that was a fun read.
TIL the origin of Courier.
Long story short:
- Some of the emails in the file dump had attachments.
- The way attachments work in emails is that they’re converted to encoded text.
- That encoded text was included - badly - in the file dump.
- So it’s theoretically possible to convert them back to the original files, but it will take work to get the text back. Every character has to be exactly correct.
Source: I’m a software developer and I’m currently trying to recover one of these attachments.
Are you having as much trouble with OCR as the article author? I would have thought OCR was a solved problem in 2026 even with poor font selection.
I wonder if they gave considered crowdsourcing this, having many people type in small chunks of the data by hand, doing their own character recognition? Get enough people in and enough overlap and the process would have some built-in error correction.
I mean the problem is that even with human eyes it’s still really hard to tell l and 1 in that font.
OCR is mostly good enough. Problem here is we have 76 pages that we need to be read perfectly, with a low fidelity input
We also have very little in the way of error correction, since it’s mostly not human readable
We also have very little in the way of error correction, since it’s mostly not human readable
This is the main point.
Most well working OCR systems have a dictionary-check pass, which goes a long way into fixing the errors.On the other hand, if all those files are the same font and size, it should be possible to tune the OCR to better match the requirements. Also reduce the possibilities to the character set used by the encoding.
I was recently using OCR for an unrelated project and it was totally unusable as is, because unlike what it expected (plain text documents), it got text on top of pictures. So now I have to find ways to preprocess and single out the text, removing the graphic lines that might be behind it, to make it readable.
Curious here, this is base 64? And what’s behind it is more often than not an image or text? And you need to do ocr to get the characters?
Maybe for the text it could use a dictionary to rubber stamp whether that zero is actually a letter oh, etc etc?
I’m curious to know what the challenge is and what your approach is.
Yes, it’s base64. And what’s behind it could be anything that can be attached to an email.
In this case, it’s a PDF. If the base64 text can be extracted accurately, then the PDF that was attached to the email can be recreated.
The challenge is basically twofold:
- There’s a lot of text, and it needs to be extracted perfectly. Even one character being wrong corrupts it and makes it impossible to decode.
- As the article points out, there are lots of visual problems with the encoded text, including the shitty font it’s displayed with, which makes automating the extraction damn near impossible. OCR is very good these days, but this is kind of a perfect example of text that it has trouble with.
As for my approach, I’m basically just slowly and painstakingly running several OCR tools on small bits at a time, merging the resulting outputs, and doing my best to correct mistakes manually.
I’m a software developer and I’m currently trying to recover one of these attachments.
🫡
Godspeed friend
There’s an iOS game about the history of fonts you might enjoy. Struggling to find it at the moment, but you play a colon navigating through time, solving various puzzles.
I’m failing to understand why or how a part of the large intestine would time travel, nor why it would be bothered to solve puzzles! 🤔
Fun fact: this guy uses fish shell.
Hell yeah, fish is great
Sounds like he also maintains it
Source? I’ve seen the bash reference manual in the files
The article author. And they state it explicitly in the footnotes.
Has anyone checked if it’s just black text on a black background. That would be in line with the competence level of Donnie’s administration.
Some of the reactions are some in an effective way, and I assume this example is one of them. The problem being evidently they didn’t think any what might be in big base64 blobs in the PDF, and I guess some of these folks somehow had their email encoded as PDF, which seems bonkers…
This is really great, dont tell this to anyone!
They are still releasing more parts of the Epstein files!
Take the advice of Napoleon: Never interrupt the enemy while they are making a mistake!
yeah, I’m always a bit annoyed when people laught at the incompetence.
Let them.
Heck, some of it might even be intentional. Don’t take away tools for leakers
I tried to leave a comment, but it doesn’t seem to be showing up there.
I’ll just leave it here:
too tired to look into this, one suggestion though - since the hangup seems to be comparing an L and a 1, maybe you need to get into per-pixel measurements. This might be necessary if the effectiveness of ML or OCR models isn’t at least 99.5% for a document containing thousands of ambiguous L’s. Any inaccuracies from an ML or OCR model will leave you guessing 2^N candidates which becomes infeasible quickly. Maybe reverse engineering the font rendering by creating an exact replica of the source image? I trust some talented hacker will nail this in no time.
i also support the idea to check for pdf errors using a stream decoder.
How big is N though?
Since there’s 78 pages, I’m guessing at least 1 ambiguity per page? Anyways, it’s dreadfully big.
2^78 is large but computers can do an awful lot per second, so if only about some the pages contain attachments 2^40-55 is something you could bruteforce in weeks if you can do millions of attempts a second
I need an ELI5 version of this. (Note: this comment is a critique of me, not the author or the content of the article.)
Edit: if “nerdsnipe” isn’t in the dictionary, it totally should be.
Some of the Epstein emails were released as scanned PDFs of raw email format (See MIME)
MIME formatted emails are ASCII based. To include an attachments, which can be binary, the MIME format specifies it must be encoded using base64. Base64 can always take binary input and return an ASCII output. This is trivial to reverse if you have the ASCII output.
However, the font choice is inconvenient because l and 1 look the same.
I’m a bit confused by the article is only discussing extracting PDFs while in actuality you can reverse any attachment including images.
I am also no expert, so a smarter person will now correct me on anything I got wrong.
Its correct
Why the pdfs contain “wrong letters” though, i havent a clue
I think this is the origin: https://xkcd.com/356/