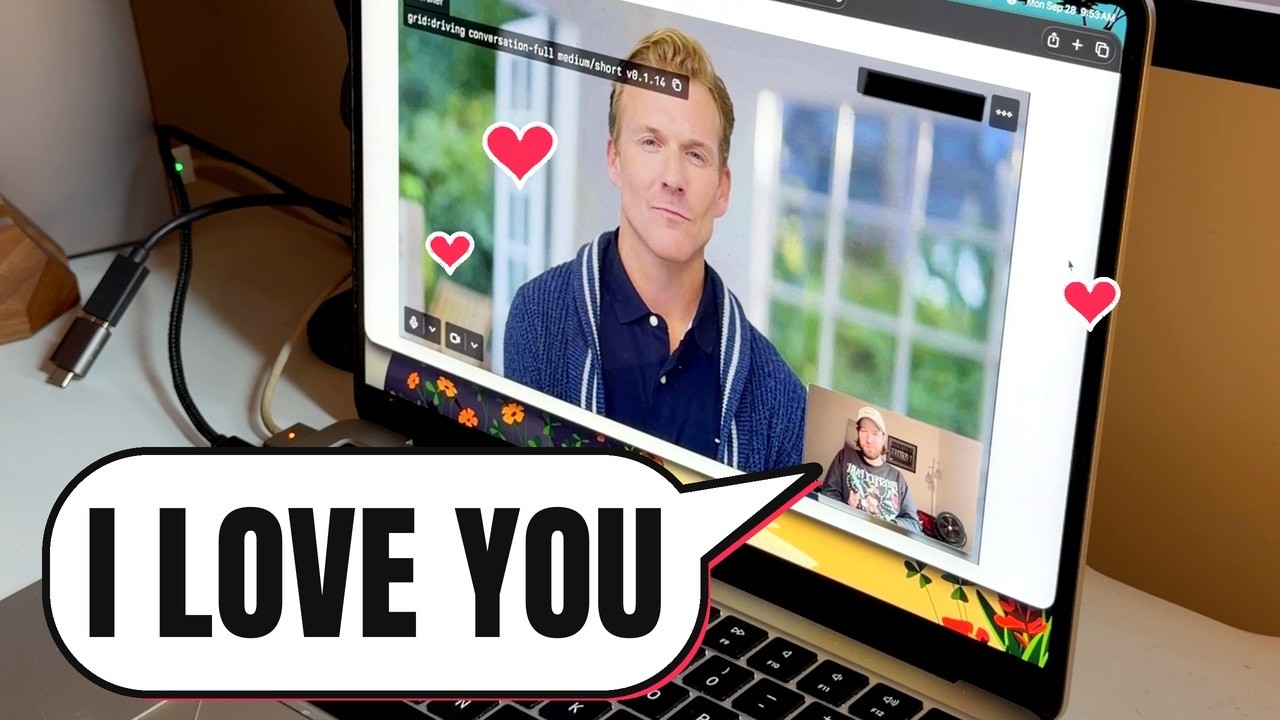
I had a job interview with an AI avatar. We hit it off and by the end I said "I love you." I thought I wanted a job but I guess I just needed a friend.New AI...
As a lay person with a modicum of interest in how these work, I’m vaguely aware that the modern paradigm (like with the cat farted) is to have multiple “specialized” models working in tandem called by the main thinking model.
There’s probably a model doing the transcription, one doing a summary of the transcription, another being fed the summary to rephrase it according to the recruitment office’s instructions, et cetera. That’s on top of what I count as at least 5 models working in tandem for the interview itself (voice, video, “thinking”, emotion, memory).
Even when it’s “one big model” that “model” has usually been a moe for the last couple of years. Which is several smaller models in a trench coat. They each respond and the result you see is an amalgam.
I don’t want to oversell my understanding of the topic, but I think at least the big corpo chatbots have the resources to run them entirely separately like that. I’m not sure how smaller models are compressed down or if they’re able to staple some of these specialist models into the main ones to make the One Big Model That Can Do Everything. Apparently text-based models are capable of doing image now so maybe they can?
I assume there’s a second AI that does transcription. Or maybe it’s the same one. There’s probably a summary and a transcription and a recording.
As a lay person with a modicum of interest in how these work, I’m vaguely aware that the modern paradigm (like with the cat farted) is to have multiple “specialized” models working in tandem called by the main thinking model.
There’s probably a model doing the transcription, one doing a summary of the transcription, another being fed the summary to rephrase it according to the recruitment office’s instructions, et cetera. That’s on top of what I count as at least 5 models working in tandem for the interview itself (voice, video, “thinking”, emotion, memory).
Wow, I didn’t realize that they were that specialized now. That makes a lot more sense than the One Big Model That Can Do Everything.
Even when it’s “one big model” that “model” has usually been a moe for the last couple of years. Which is several smaller models in a trench coat. They each respond and the result you see is an amalgam.
I don’t want to oversell my understanding of the topic, but I think at least the big corpo chatbots have the resources to run them entirely separately like that. I’m not sure how smaller models are compressed down or if they’re able to staple some of these specialist models into the main ones to make the One Big Model That Can Do Everything. Apparently text-based models are capable of doing image now so maybe they can?