How much of our water, electricity, tax breaks, and public land does it use?
Yes!
All the investors know it’s a massive money sink right now. The goal isn’t for “everyone” to get to use AI.
It’s to get so many people used to using AI that businesses like law offices and hospitals and ither corporations so ingrained and built around having AI l, while leaving so many graduating college students useless without AI that businesses will be reliant upon it, no matter what costs of it they will have to absorb.
In five years there won’t be a $200 plan. There will be a $15,000 plan per person and businesses will pay it because they won’t be able to do well without it.
deleted by creator
Law offices, hospitals, and insurance companies are not going to set up their own servers, localize an AI, and upload all the custom data sets they need into a pre trained locally hosted model. Everyone could easily host their own cloud backup system as well, but no one does it.
But yes. That’s there plan. It’s been done multiple times before amongst things. It’s how busses eliminated trolleys, how ride share beat out taxis, and how Walmart sells the cheapest Coke. Amazon does it as well. It’s a variation of predatory pricing. It’s common as hell. Supposed to be illegal, but seldom does anyone get in trouble for it. Crooked government that works for the wealthy n all.
deleted by creator
Since when has stupid ever stopped anything?
I think there may also a horizontal scheme as monopolies take on a global scale. Those businesses that sell in bankruptcy due to high tech costs could be gobbled up by the biggest AI-native competition. It’s a leap but maybe in a decade your optometrist is replaced by an ai kiosk with a remote technician?
Maybe then he would give me the prescription I paid for…
“I can’t quit my job because I’ll lose my
health insuranceAI access.”
I’d rather save earth
Then don’t use the internet because everything has Ai. Google has it, every browser has it installed, almost every shopping site automatically uses Ai results, the news feed on Google is all Ai results, the questions that are the most asked on Google are now Ai driven.
Main point of environmental destruction is using the LLM’s but nearly everything is using Ai and it’s hard to outrun it and a lot of things are making it hard to opt out and I wouldn’t put it past them to make it so they can make you pay to opt out of Ai in the future for a premium browser with the ability to disable Ai otherwise you’re stuck with it kind of thing.
I hate what it’s doing to the environment too but it’s not going away unless everyone in neighboring communities decided to bulldoze them and use their wrecking balls to destroy them. Emps aren’t hard to make happen.
If people wanted to destroy them they would. If people really didn’t want them they’d destroy them.
every browser has it installed
Not Waterfox!
Use Firefox without AI and don’t use google search engine
What bubble have you been living in? Almost none of my apps have any kind of AI… You can easily ditch it by using a Firefox fork, or any privacy Chromium fork, or even Chromium itself. Saying “Then don’t use the internet” is somewhat of a defeatist sentence, just stick to good websites/programs and you’re good.
I should’ve added a 🤪 to that because that was meant to be light not in a fuck off kind of way but more of a you gotta be kidding me this shit keeps expanding kind of way.
Oh
I dunno, man. I’ve blown $200 on worse things.
The total I spent on AI is $0. How much AI can I get for that?
Quite a bit if you actually wanted to use it. Opencode offers enough usage for free that you could create full apps from it lol, caveat being that their free plan usage is being used to train the models you use. But then everyone is probably doing it on their paid plans as well.
I would prefer none, but there’s AI being forced on us everywhere these days.
If you keep opening a new private tab and starting new conversations with chatgpt, your usage including uploads is free!
Also you can just switch to any other provider when you finish your free daily quota!!
a little bit per maybe
those who subscribed should set up bots to use that full potential
let AI write that bot
Hopefully it doesn’t crash when the usage goes up a bit.
Do you want a Butlerian Jihad? Because that’s how you get a Butlerian Jihad
DEFINITELY NOT A BUBBLE EVERYBODY NOTHING TO SEE HERE
Who cares? Only morons use it.
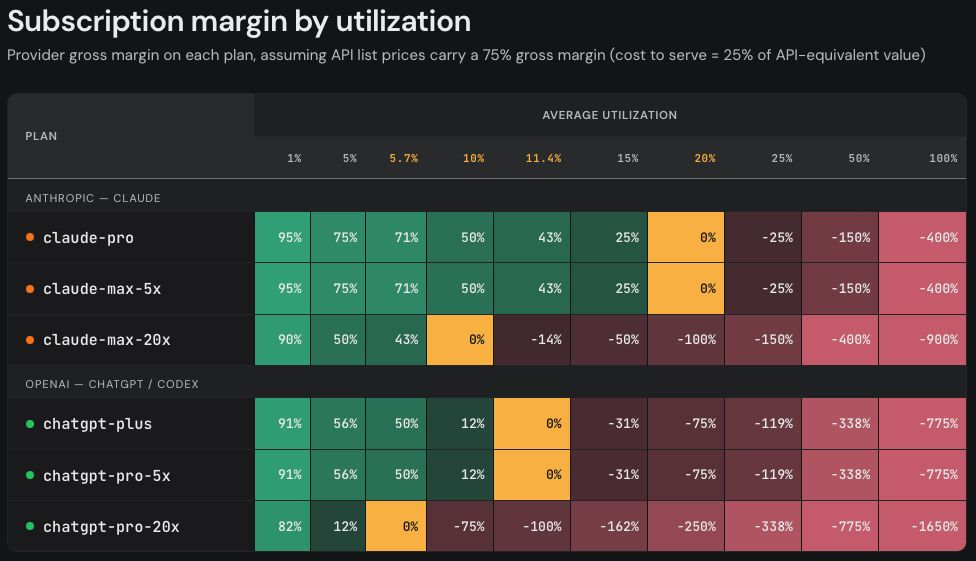
Here is the second part of the table btw, with an illusory 75% margin on API pricing:
Well, I guess I’ll buy that subscription then
Just checked Api pricing: it’s 30USD for million output tokens. Heavy usage will absolutely go into hundreds of dollars of costs, input tokens are $5/1mil so if you input files and long context it’s going to get even more expensive, potentially upwards of $1000 per month.
Headline is innacuralte. Customers who purchase a $200/month subscription, can save up to $13800 on token costs compared to “a la carte” token pricing. Open AI does lose over $1 per $ in revenue, but this is more a function of them having too much compute, and very high training costs, rather than a loss per gpu hour on tokens served, it should stilll be a loss for OpenAI:
Open source model pricing per gpu hour, ranges from 80% margins at high batch saturation per user (low tps per user) to 50% at concurency of 8, to loss at fewer user requests per gpu. https://inferencex.semianalysis.com/compare/deepseek-r1-b300-vs-h200
OpenAI has very high prices, and too much compute. They would likely lose $6000 per user who maxes out their $200 plan, and certainly over $1000 per user.
Totally not a bubble, honest guv!
assuming API pricing
API pricing is not what it costs openai to offer the inference.
API pricing is what they’re currently selling their inference, with profit included in price.
“But if the user didn’t get a subscription, he would have spent $14k in token” is a wrong assumption.
The user is wasting the tokens on useless tasks because they’re free to him, but once he has to pay them, he wouldn’t ask to generate 100 images of a toilet eating carrots anymore
If you’ve got a toy project that you want “AI” to give you a hand with, do it now.
Pretty soon all these companies are going to have to pay for all that investment in compute resources they’ve been busily soaking up over the last few years, and then they’re going to have to pay back their investors, and then they’re going to have to try and make a profit
This is the golden time for cheap commercial AI. Already the noose is starting to tighten, and it will never again be as cheap as it is now.
Yes we’ve begun to track “token use” all over my company so it doesn’t spiral out of control, as it easily can do when you have agents managing agents connecting to MCP servers that themselves use the models to generate responses. The engineers around me say that they basically have multiple agents cranking full time and just keep an eye on them every so often. They will even queue up things to run overnight to make use of the time. They never actually close their laptops. This is an insane amount of usage, well beyond what anyone can do in the ChatGPT application by typing with their fingers, and there’s no way it can continue like this.
Another way to look at it would be “if you’ve got a toy project to practice coding without AI on, do it now” before that is the only option.
This is the golden time for cheap commercial AI.
I suppose, but small open weight models with more advanced coding frameworks optimized for them are catching up fast and you can do it privately at home on a mostly affordable consumer graphics card.
If you have solar it’s basically free, minus the graphics card CapEx you may want for gaming anyway, as well as some setup time and a bit of patience.
What’s your setup, if I may ask? I’m using llama.cpp router with vscode kilo.ai and qwen3.6-35B-MoE-MTP as a model mostly. It’s surprisingly good as a coding assistant, but I think you have to know what you are doing and know your stuff(aka be an experienced developer) to make it useful. just letting it vibe leads to crap code
just letting it vibe leads to crap code
Yup, vibe is occasionally useful for proof of concept stuff, but disastrous for maintainability, security, readability, or large codebases. Without experience it’s still a foot gun for anything even slightly serious.
Best approaches for a learner are to consider it autocomplete that needs research. Look up what it’s suggesting, see if it’s hallucinating, with luck it’ll point you in a useful direction where you can learn a good solution, as it has no idea what that is. Also makes a pretty good rubber duck for hashing out architectural decisions, finding alternative approaches etc, though you’ll have to point it at a web search for that. Spin up an e.g. vane instance for this, as small models don’t have enough world knowledge. Use it to write (or preferably copy from its system prompt examples) boilerplate and unit tests, perhaps descriptive comments (doublecheck).
One thing to do is put everything you learn about coding style into your system prompt as they’re dogshit at consistent style without significant beatings around the head. Finding your own comfortable, consistent style is super useful for future readability. The joke about when I wrote this only God and I understood it, now only God does, will come clear in a month or two. Learn to work around it. Simple beats fancy unless you truly need the speed.
While I do use agent iterative approaches, probably best to approach that organically as you grow, monsters lurk there. If you must, containerize / vm / isolate the hell out of something like opencode to muck around with.
FWIW I still write most of my code by hand, it’s simpler and more consistent, but I’m keeping an eye on the development of LLMs, and I will let it write scut code (that I edit later). Code and Mathematics are super structured languages, pretty much ideal for large language models, so I can see them maybe, eventually getting good. More general thought, not so much without significant architectural upgrades.
While this advice is true for all models, when it comes to agentic tasks (add this small feature/write this test harness/find bugs/suggest improvements), open source models are still way behind, vibe code or not.
Claude Fable or even Opus in an editor like Zed have a 1 million token context window and will “think” through the goals of the application, test their changes, work through debugging processes the way a programmer would, stop to ask for clarification, check diagnostic tools and linters, prompt to run test code, etc.
Llama, Gemma and Qwen etc. Do lack a lot of the world knowledge to get the goals of the application, but they also just don’t have the debugging skills, won’t test their code, don’t always tool call correctly, get confused as the context increases and nobody has enough vram to run on large context sizes locally.
They can do autocomplete on small functions but aren’t really there for more complex tasks.
On top of that, the biggest problem is that the best open source models are trained and released by the same giant tech conglomerates that have an interest in not competing with their own products. Qwen is Alibaba, Llama is Meta, gpt-oss is OpenAI. Even the more “independent” ones, kimi (Moonshot) and GLM (z.ai) are mostly funded by Alibaba and Tencent. They’re released for research and marketing purposes and to please their corporate backers with inflated stock. Almost nobody has the resources to train new models from scratch. People make lots of merges and fine tunes but AI is not democratised the way that traditional programming tools have been.
Maybe some day there will be enough cheap compute for open source communities to pool together resources to build competing models but they’re not really there yet :(
Context management is a huge part of making smaller models viable (and likely a big part of making frontier models better). Tricks like structured context libraries for thinking improve things a lot, I like approaches that output things like an Obsidian vault that let you dig in and correct bad assumptions easily, even if it’s a bit slower. It’s a useful deliverable that can (mostly) be reused with updated models.
Things like ‘the debugging skills, won’t test their code, don’t always tool call correctly’ are tangibly improving model to model, framework to framework, and are problems that will be solved in time, but yes they need handholding ATM.
Things like
test their changes, work through debugging processes the way a programmer would, stop to ask for clarification, check diagnostic tools and linters, prompt to run test code
are mostly down to framework, not model (except for failing to tool call, which is improving), and falling at a respectable rate.
That said, sure, frontier models get more in one go, personally I’m fine with only a 3-4x force multiplier instead of 10 to keep it local, but YMMV. For a business with resources for a bigger server it’ll be more like 8 times. Remember that some businesses handle sensitive data and can’t (or damn well shouldn’t) use frontier models, so the market is there.
Maybe some day there will be enough cheap compute for open source communities to pool together resources to build competing models but they’re not really there yet :(
Not wrong, decentralized inference is mostly solved (with latency penalties), but without decentralized training true democratization will remain out of reach. Hopefully a breakthrough will ensue, but until then we are dependent on the kindness of corporations (or them rugpulling competitors).
This could also be a part of the RAMpocalypse thing, ‘if there’s not a moat I’ll fucking dig one, damn everyone else’ (and damn SamA). I doubt that’s sustainable long term, but it might get them through to IPO, more’s the pity.
Yes, it’s trending in that direction, and I’ve been experimenting with pretty small models on my PC as I don’t really have the hardware to go large. If you’ve got the coding chops to set it up, it’s definitely something to keep an eye on.
There’s actually scope for someone to set up / sell local compute hardware+software packages, similar to all those coin miners. Give the end user a way to update models, or push models out to them or something, it seems it would be a good middle ground between manually typing code like a peasant and total corporate AI apocalypse.
There’s actually scope for someone to set up / sell local compute hardware+software packages, similar to all those coin miners.
I think that’ll be a viable target in the future, and have little doubt some are jumping on it already. However, I also think it’s too much of a moving target currently, a near optimal setup changes almost entirely month to month.
I find myself targeting last months setup, as then there’s enough literature out there to get it set up in a day or two and most of the kinks have been worked out. Otherwise, I lose too much coding time to debugging the bleeding edge.
IMO, at the moment, if you’re not capable of setting it up yourself you likely don’t have the experience to use it reasonably safely nor an adequate understanding of its limitations. You’ll find yourself using more time fixing the blunders than you gain, and / or the project will spiral out of control in maintainability, security, readability, and so forth. You could get away with small projects written as ‘write only’ code ala Perl though, keep the prompts and tests, when it needs to change rebuild with the newest hotness. Inefficient and unsatisfying though.
Yeah they’ve been pushing Claude code at work for us non coders jobs to come up with stuff that would help us. We’ve gotten a few surprisingly useful programs out of it, but our assumption is perfect them now before pricing goes through the roof. We are also only creating programs that do not require ongoing AI use. Just a bunch of relatively simple things that make our jobs easier.
I am still pushing my boss for some local hw as I think as a group we’ve spent a couple grand in the last month and that is the least of my reasons for wanting a local llm vs subscription.
Unless there are actual major efficiency innovations. But yes, current LLMs are sold cheaper than what they cost
Sounds like it’ll never be worth it.
In five years once this RAM nonsense is over you’ll be able to run a comparatively high quality local LLM for very little money. I can’t see how these companies will ever make their money back.
If manufacturers are willing to sell components to us in five years that is.
Of course if the colllapse happens before then the story might be different…
🤞
I’m slightly optimistic that manufacturers will return to the retail market eventually. Every AI company is racing to hyperscale right now but there will be a point where the infrastructure is built and at that point the growth will slow down quite a bit. In that scenario there will be ongoing demand for components to be replaced as they become obsolete but I can’t imagine the demand will be the same level it is right now as everyone rushes to build.
That’s assuming this all works the way they want it to. If the economics aren’t viable and the bubble bursts…
“Hyperscale” is utterly meaningless MBA jargon at this point. Equivalent of verbal slop from industry shills and CNBC/Bloomberg sell side simps.
Sorry if that’s true. I understood the word to mean aggressive growth at any cost to try and shut out competition before they can get established.
Their Datacenter buildout doesn’t work they want to. Most projects are very much delayed, and those that even started getting built are over budget. OpenAI and Anthropic will collapse in the next years, and this is coming from someone who absolutely sees the good things about the technology itself.
OpenAI and Anthropic will collapse in the next years
Stop, I can only handle so much good news!
There is no way, absolutely NO WAY to recuperate the amount of cash burnt on those two companies, and that is not even counting the amount of AI Startup whose cash is currently flowing towards to those two.
Sounds like price hikes to communicate costs are coming and resources are going to be redistributed to productive uses.
Nice try, I still ain’t gonna pay. OpenAI can go bankrupt without burning my money
See gym and carwash memberships
Is there a carwash membership???
Yeppers. Sign up for a monthly subscription with your cc, and no real way to cancel! “Unlimited”* car washes, so why would you ever cancel? You’re gonna want a clean car
Yes if you want to ruin your car (assuming we’re talking about the brush type carwash). It wears down the clear coat if you do it a lot.